Driver Attention Tracking and Analysis

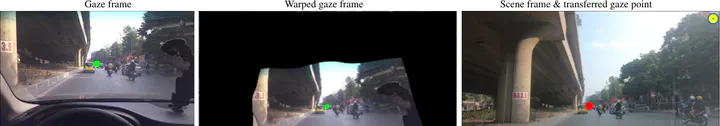 Transferring the driver’s point-of-gaze from the face camera into the road scene.
Why this problem
Knowing what a driver is looking at — not just where their head is pointing — is the difference between a monitoring system that can warn about a missed traffic sign and one that cannot. The usual answer is eye-tracking glasses, which are expensive, intrusive, and impractical for mass deployment. They also only tell you what the driver did look at, never what they missed in the scene.
What we did
We built a dashboard-mounted system that needs only two ordinary cameras: one on the driver’s face, one on the road. The core is a convolutional network that reads both images at once and predicts the driver’s point-of-gaze directly in the scene frame.
The hard part is that the geometry between driver and cameras drifts constantly — even within a single drive. Rather than asking the driver to recalibrate, the network includes a camera calibration module that learns an embedding of the driver–camera spatial configuration and is trained end to end with the rest of the model. This module measurably improves gaze accuracy.
We also released a large-scale in-situ dataset: real urban driving sessions with synchronised face, scene, and gaze video, and over one hundred thousand image pairs annotated with points of gaze — addressing a gap no existing gaze dataset filled.
Result
Mean prediction error of 29.69 pixels against a 1280×720 scene camera, outperforming the baseline methods we compared against.